Four markets, one voice, built from zero
Two markets where nobody knew the category existed, opened in sixty days. Then one message held across four countries without flattening any of them.
- Client
- A European supply chain services group
- Markets
- Two pilot markets, then four
- Engagement
- 12 months, ongoing
- What we did
- Market validation, positioning, four-country content engine, SEO, paid media, business influence
- The result
- Category presence built from nothing in two months, then one narrative running across four countries
A European supply chain group needed to open two markets where nobody knew the category existed, then hold one coherent message across four countries without flattening any of them. The local model built for the smallest market became the standard for the region.
Nobody was searching, because nobody knew the category existed. So the job was to teach a market what the service is and prove commercial demand at the same time, on a budget small enough to stop. Two markets responded almost identically, and that consistency is what justified funding the other two.
The challenge
The group was strong operationally and close to invisible commercially in the markets it wanted next.
In two of them the category itself was unfamiliar. Buyers were not choosing a competitor. They did not know the service model existed, which is a harder problem than competition and much harder to brief. No search demand to capture, because nobody was searching.
In the two established markets the problem inverted. One faced long-standing alternatives and had gone years without consistent marketing presence, so the brand had slipped quietly out of the consideration set. The other had awareness without positioning.
Four markets, four different problems, one group narrative that had to survive all of them.
What the problem actually was
The brief described a visibility problem. It was not one.
Visibility assumes the market already knows what it is looking at. Running awareness campaigns into a category nobody understood would have bought impressions and taught nobody anything. The real problem was category education under commercial pressure: teach a market what the service is, and prove commercial demand, at the same time, before anyone funds the years of presence that category building normally takes.
That reframe changed the engagement. We did not propose a campaign. We proposed an experiment designed to produce evidence a board could act on, and we said in advance what result would justify stopping.
The second diagnosis mattered more over the year. Four local teams held real market knowledge and had no shared architecture for using it. Every country was solving the same problems separately. The scarce asset was never content. It was a way for four teams to stay coherent without any of them being overruled.
What we did first
A short validation pilot in the two unfamiliar markets, on a deliberately modest budget.
It was scoped as a test rather than a performance campaign, and we were explicit about that with the client. The question was not how many leads can we generate. It was whether the market responds at all, who responds, and what it costs to find out.
One message was tested identically in both markets, so the variable was the market and not the copy. Each platform was given a distinct role so we could see which part of the funnel it was actually doing. And there was a hard stop, so a test could not quietly become a permanent budget line.
What that proved
The markets responded, and they responded almost identically.
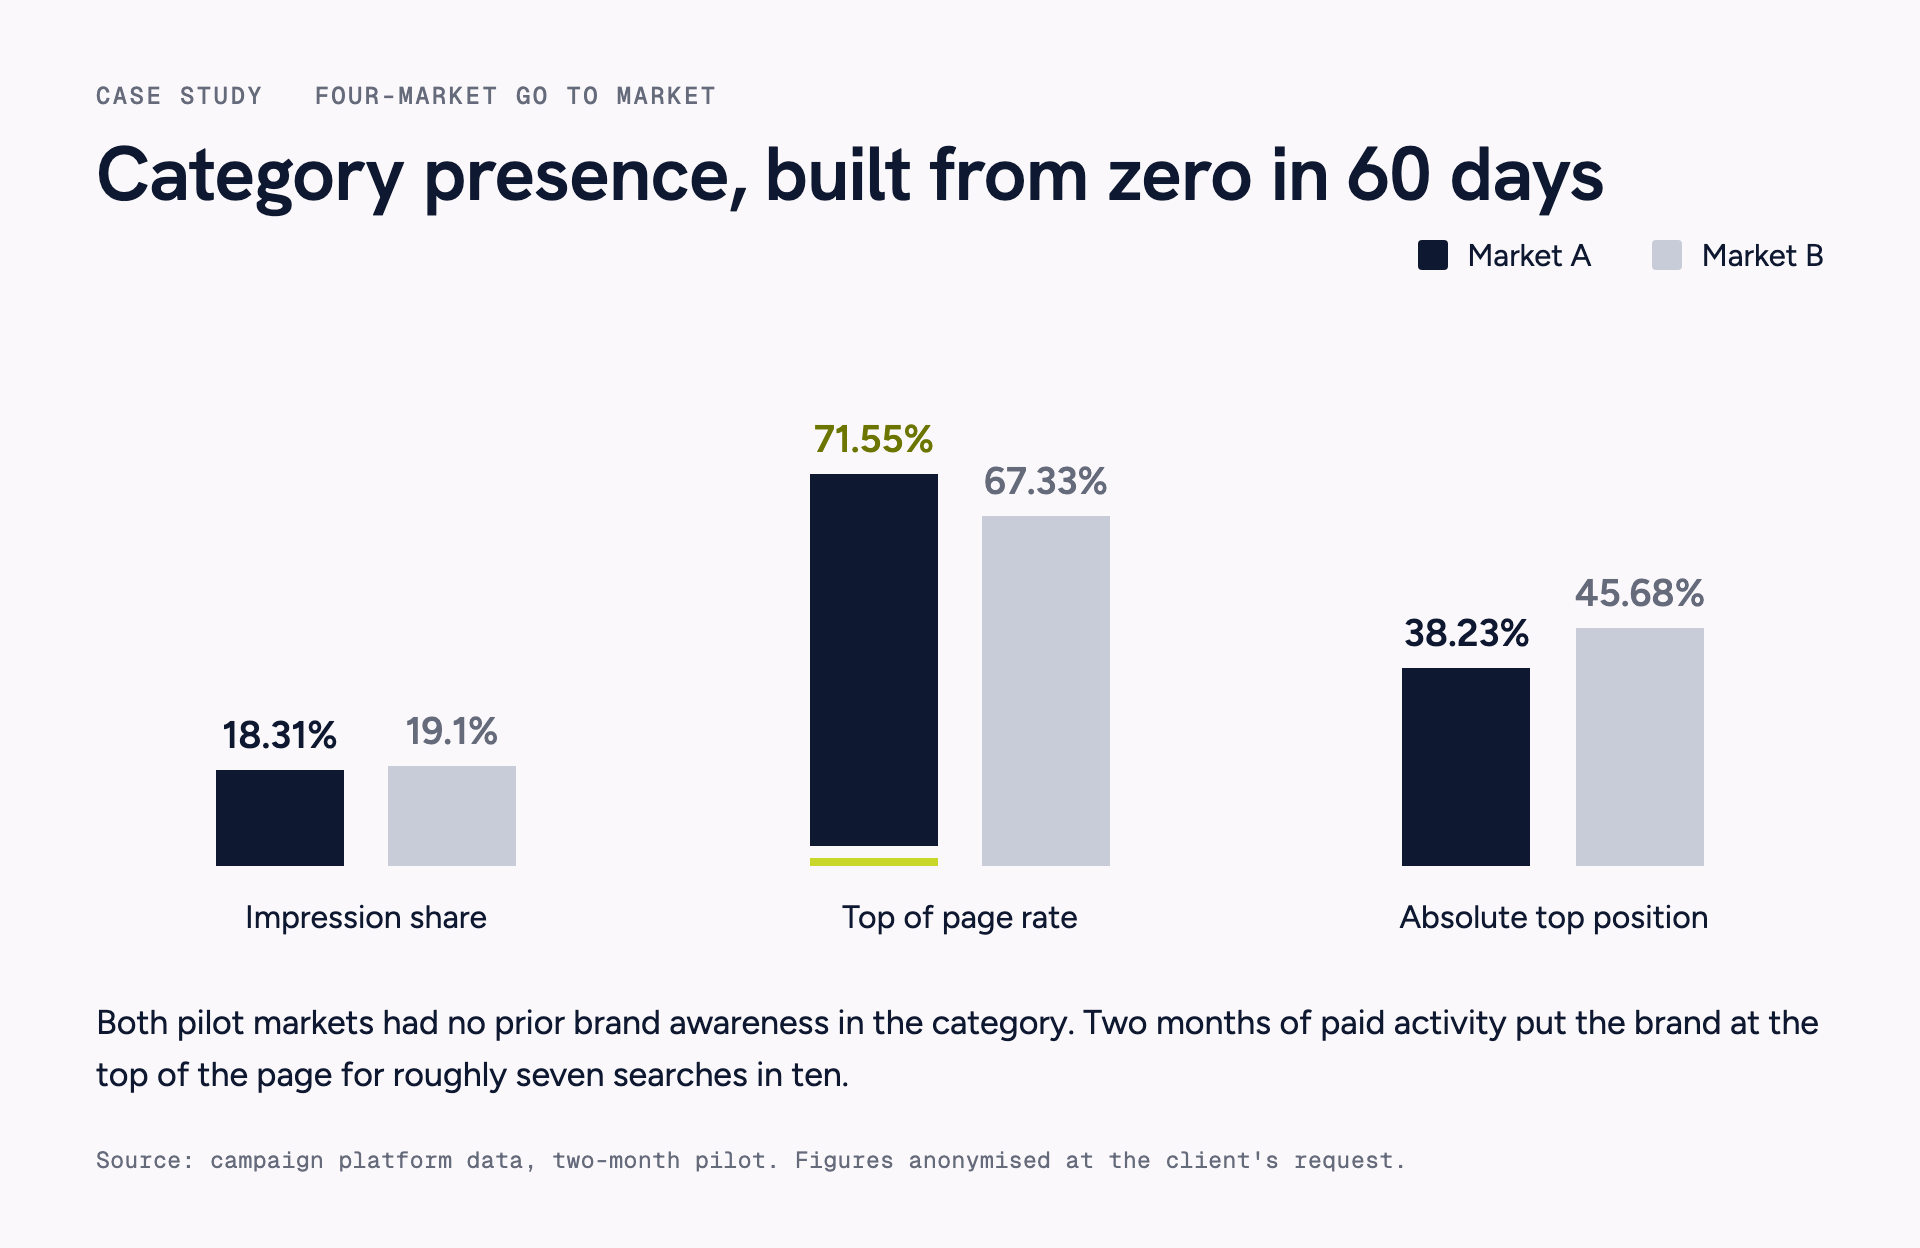
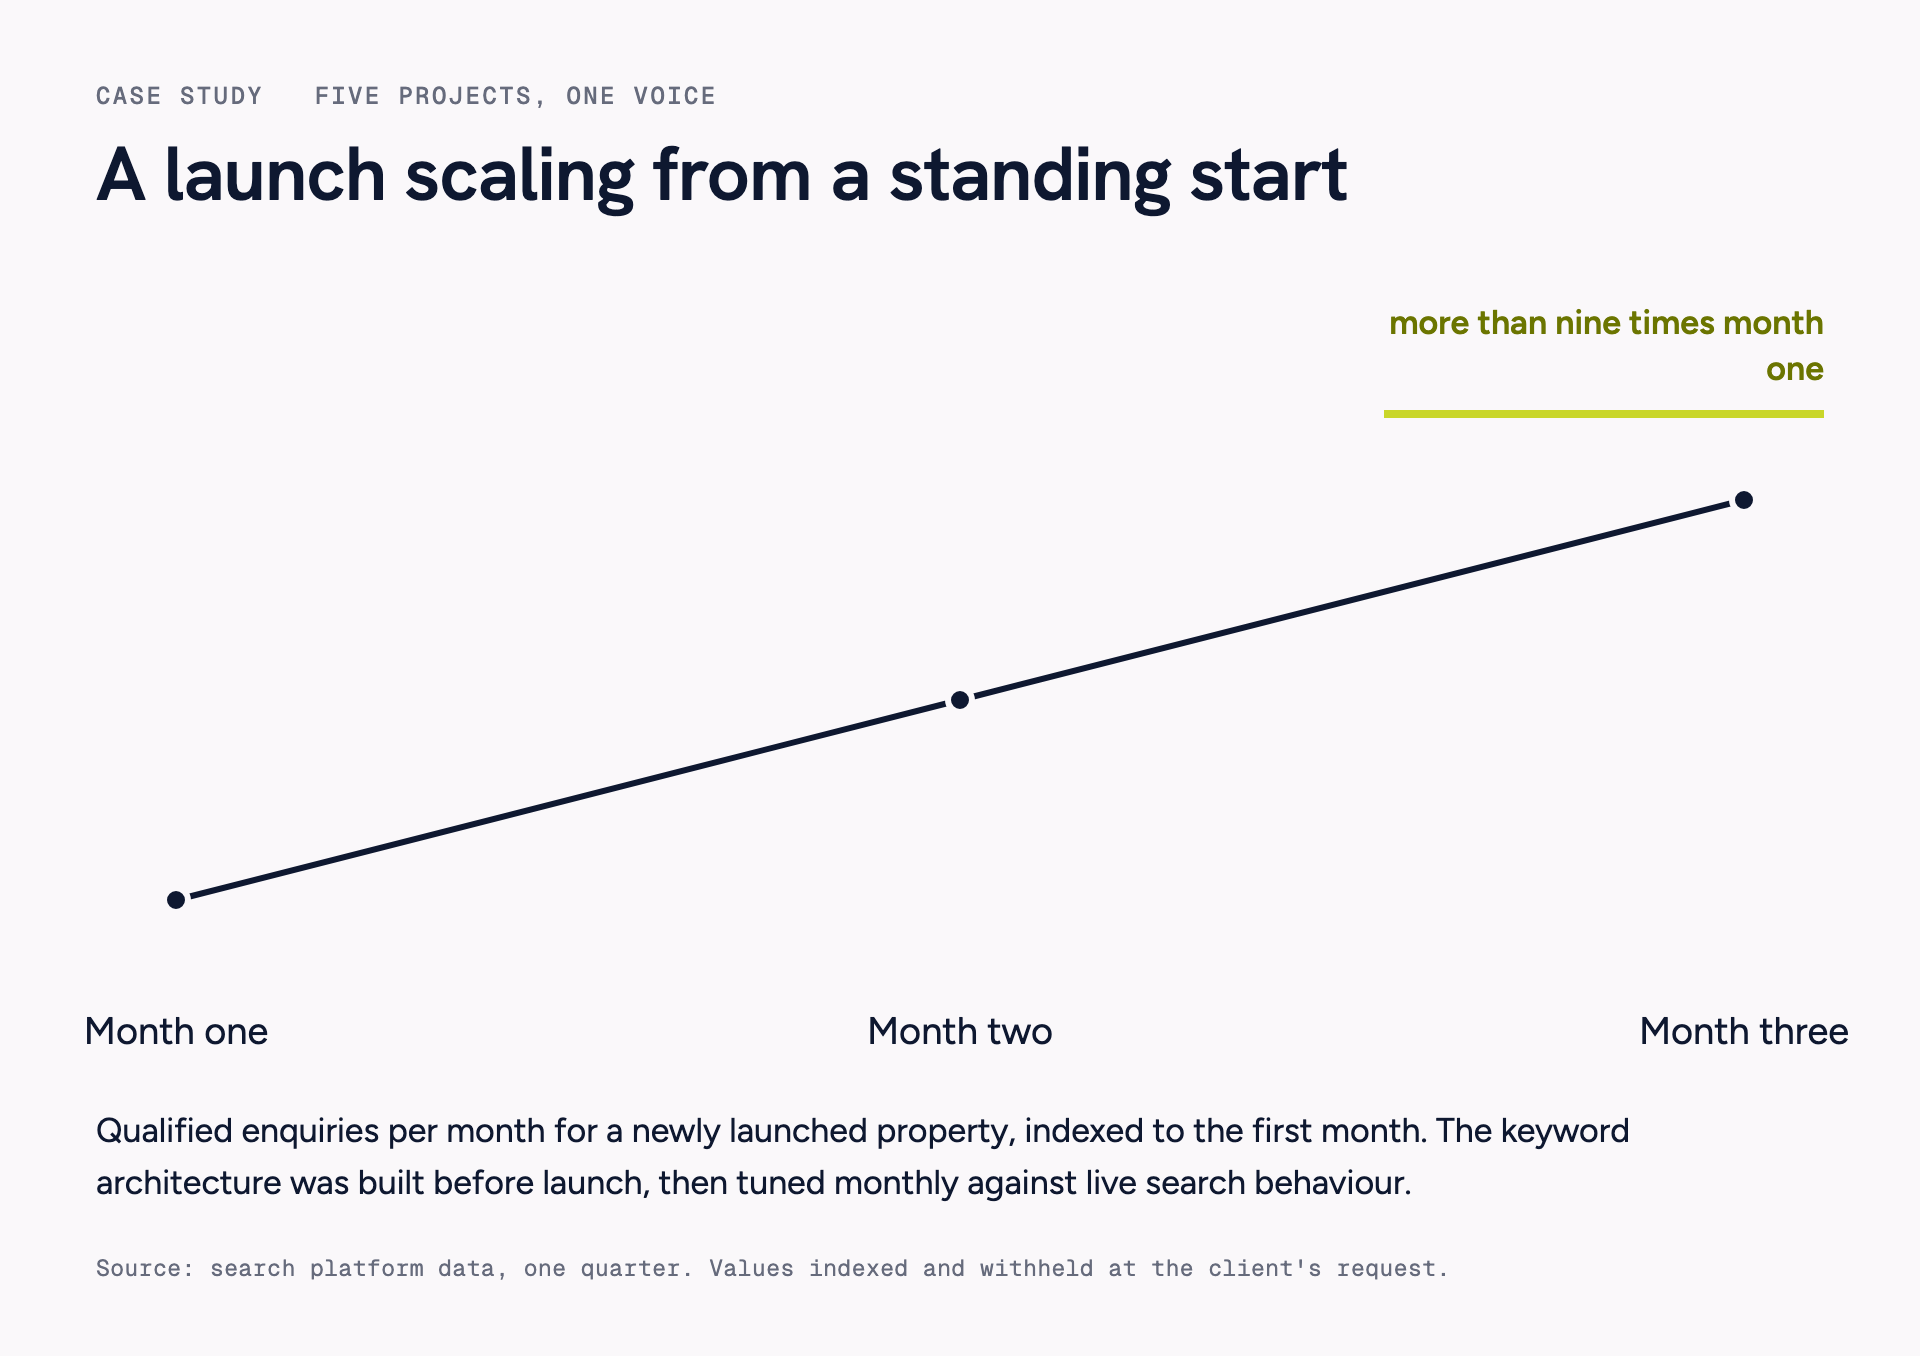
Two countries, different languages, different competitive conditions, different maturity, and category search presence within a point of each other inside sixty days. That consistency was the finding, not the level. It suggested the message was doing the work rather than local circumstance, which is precisely what you need to know before committing budget to two more countries.
What it did not prove. A short pilot cannot model a pipeline, the sample was too small for meaningful attribution, and one channel could not be defended on its own numbers. We put all of that in the report. A pilot that produces only good news has not been designed properly.
Scaling it
Phase two went from two markets to four, and from testing to building.
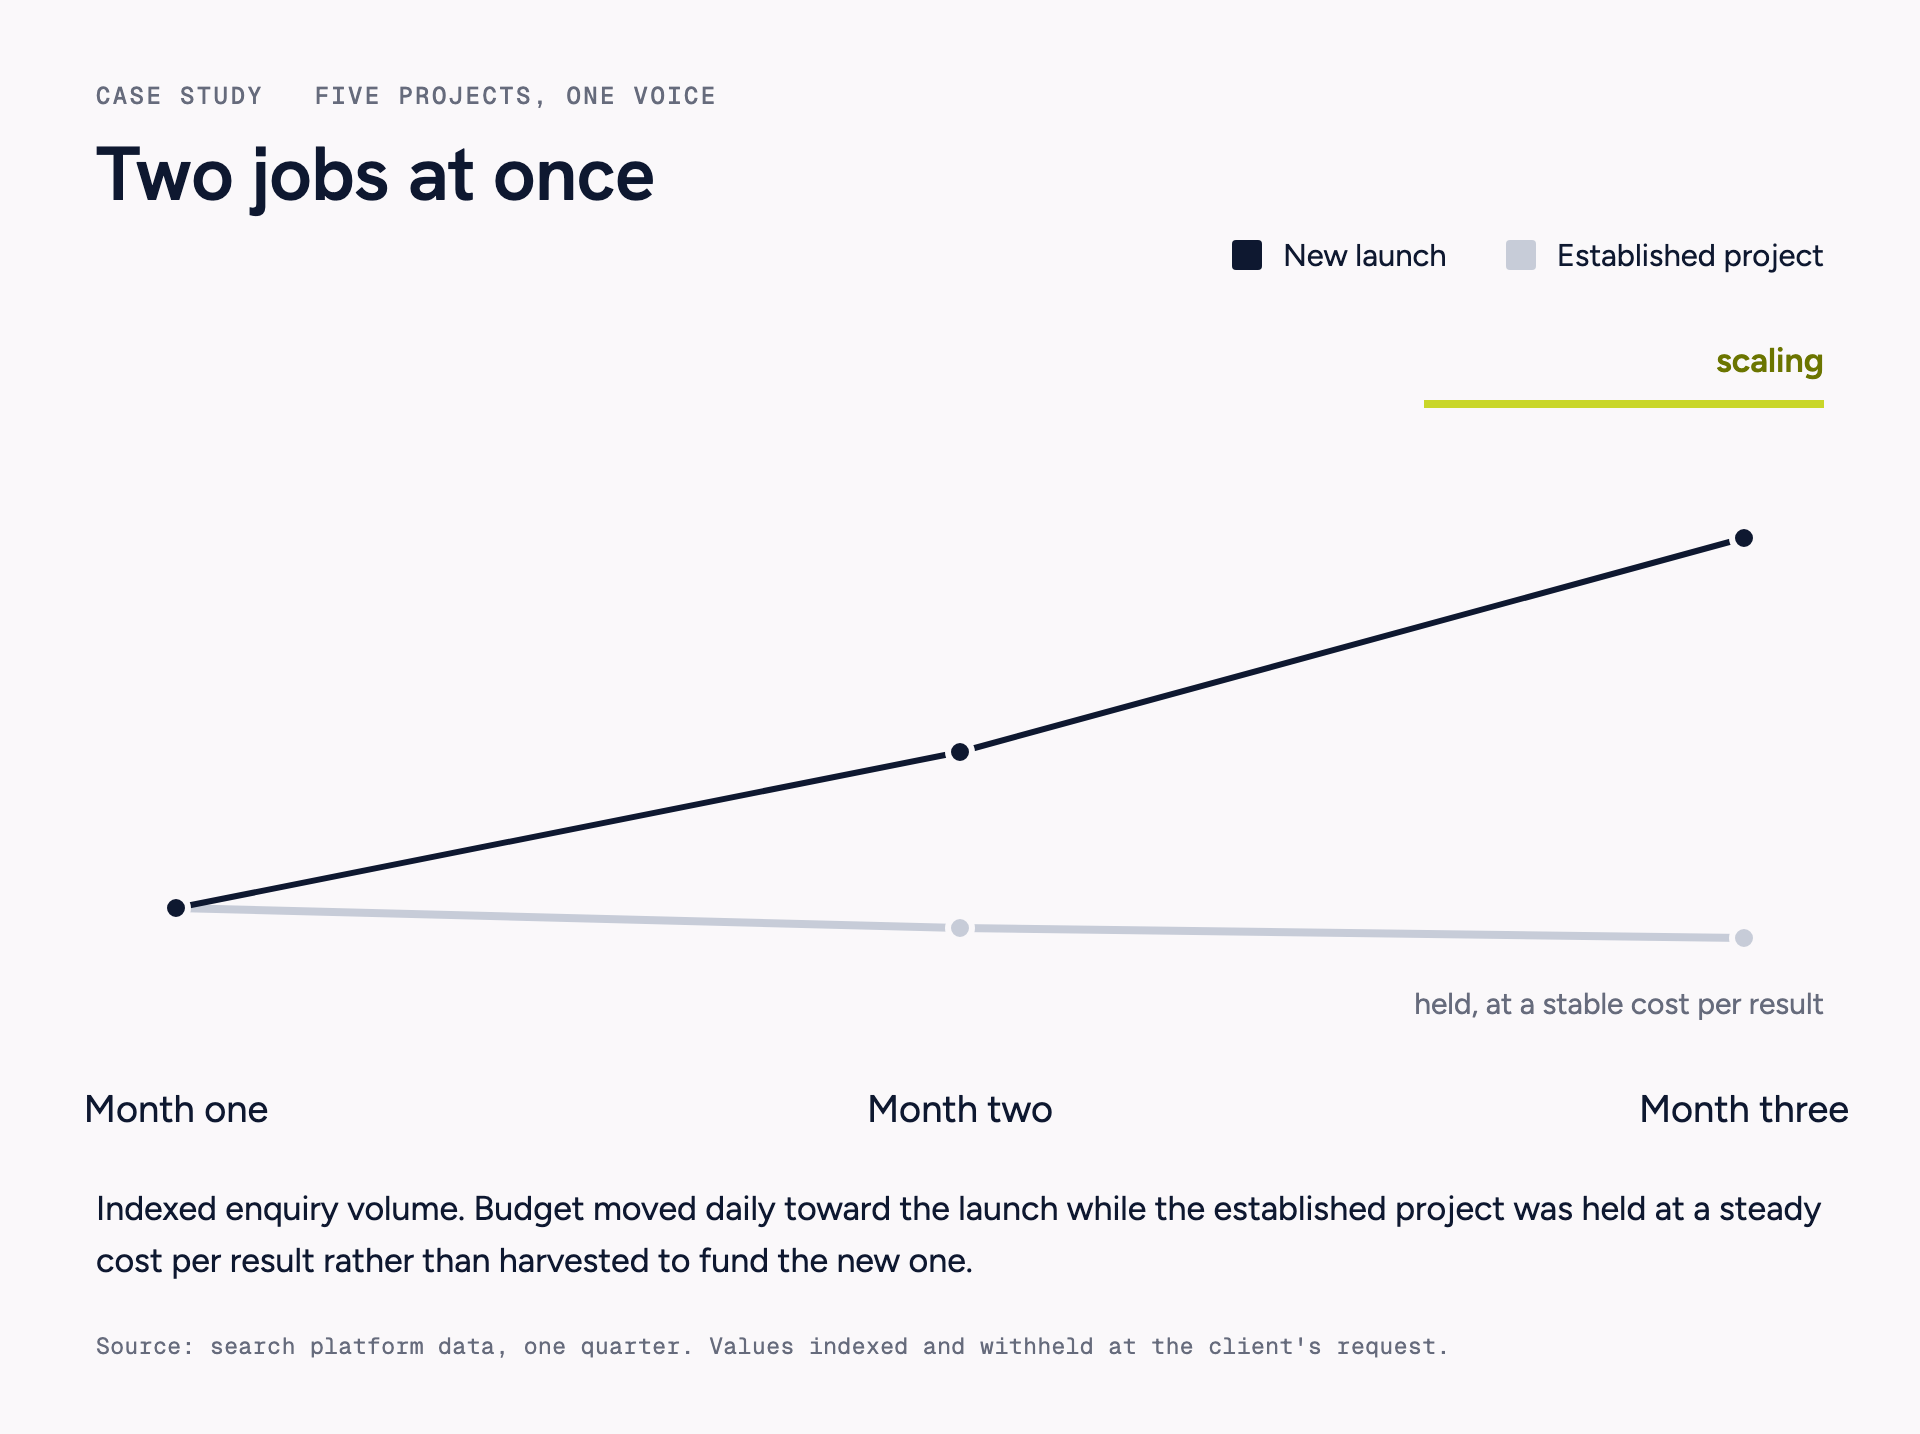
At the centre was a messaging framework run at roughly 60% shared, 40% local. The shared part carried the group’s positioning, the category argument and the non-negotiables. The local part belonged to each country: examples, references, terminology, tone, and the freedom to say a thing differently because the market hears it differently.
That ratio was a decision, not a compromise. Push shared much above it and local teams stop recognising themselves in the output, then quietly stop using it. Drop below it and within six months you have four brands.
On top of that ran a weekly publishing rhythm per market, regular newsletters, search-led articles, and pillar content built for long-term authority rather than short-term traffic.
Working with their team
This is the part most agencies leave out, and it decided whether any of it worked.
We met more than thirty of their colleagues over the year, in person and online: country directors, local marketing, operations, technical experts across all four markets. Not onboarding. The method.
We held strategy and coordination as the central point, content production, search and analytics, social management, newsletters, paid architecture and the editorial calendar. Their central team held final sign-off on messaging, topic priorities and alignment with group positioning. Their local teams held the things we could not: market insight, validation of language and tone, local examples, and the final go-ahead to publish in their own market.
That last one matters. Local teams had a veto, not a review. It slowed publishing down, and it is the only reason the programme did not collapse into four polite translations of a single head-office plan.
The model that travelled
The most useful thing we learned all year came out of the smallest market, and it was not a strategy. It was a format.
We filmed the client’s own people, at their own site, talking about their own operations. No studio, no script, local language, real faces. It was built to solve a narrow problem: prospects in that market were not certain the group had a genuine local presence, and the sales team was spending the first ten minutes of every call proving it did.
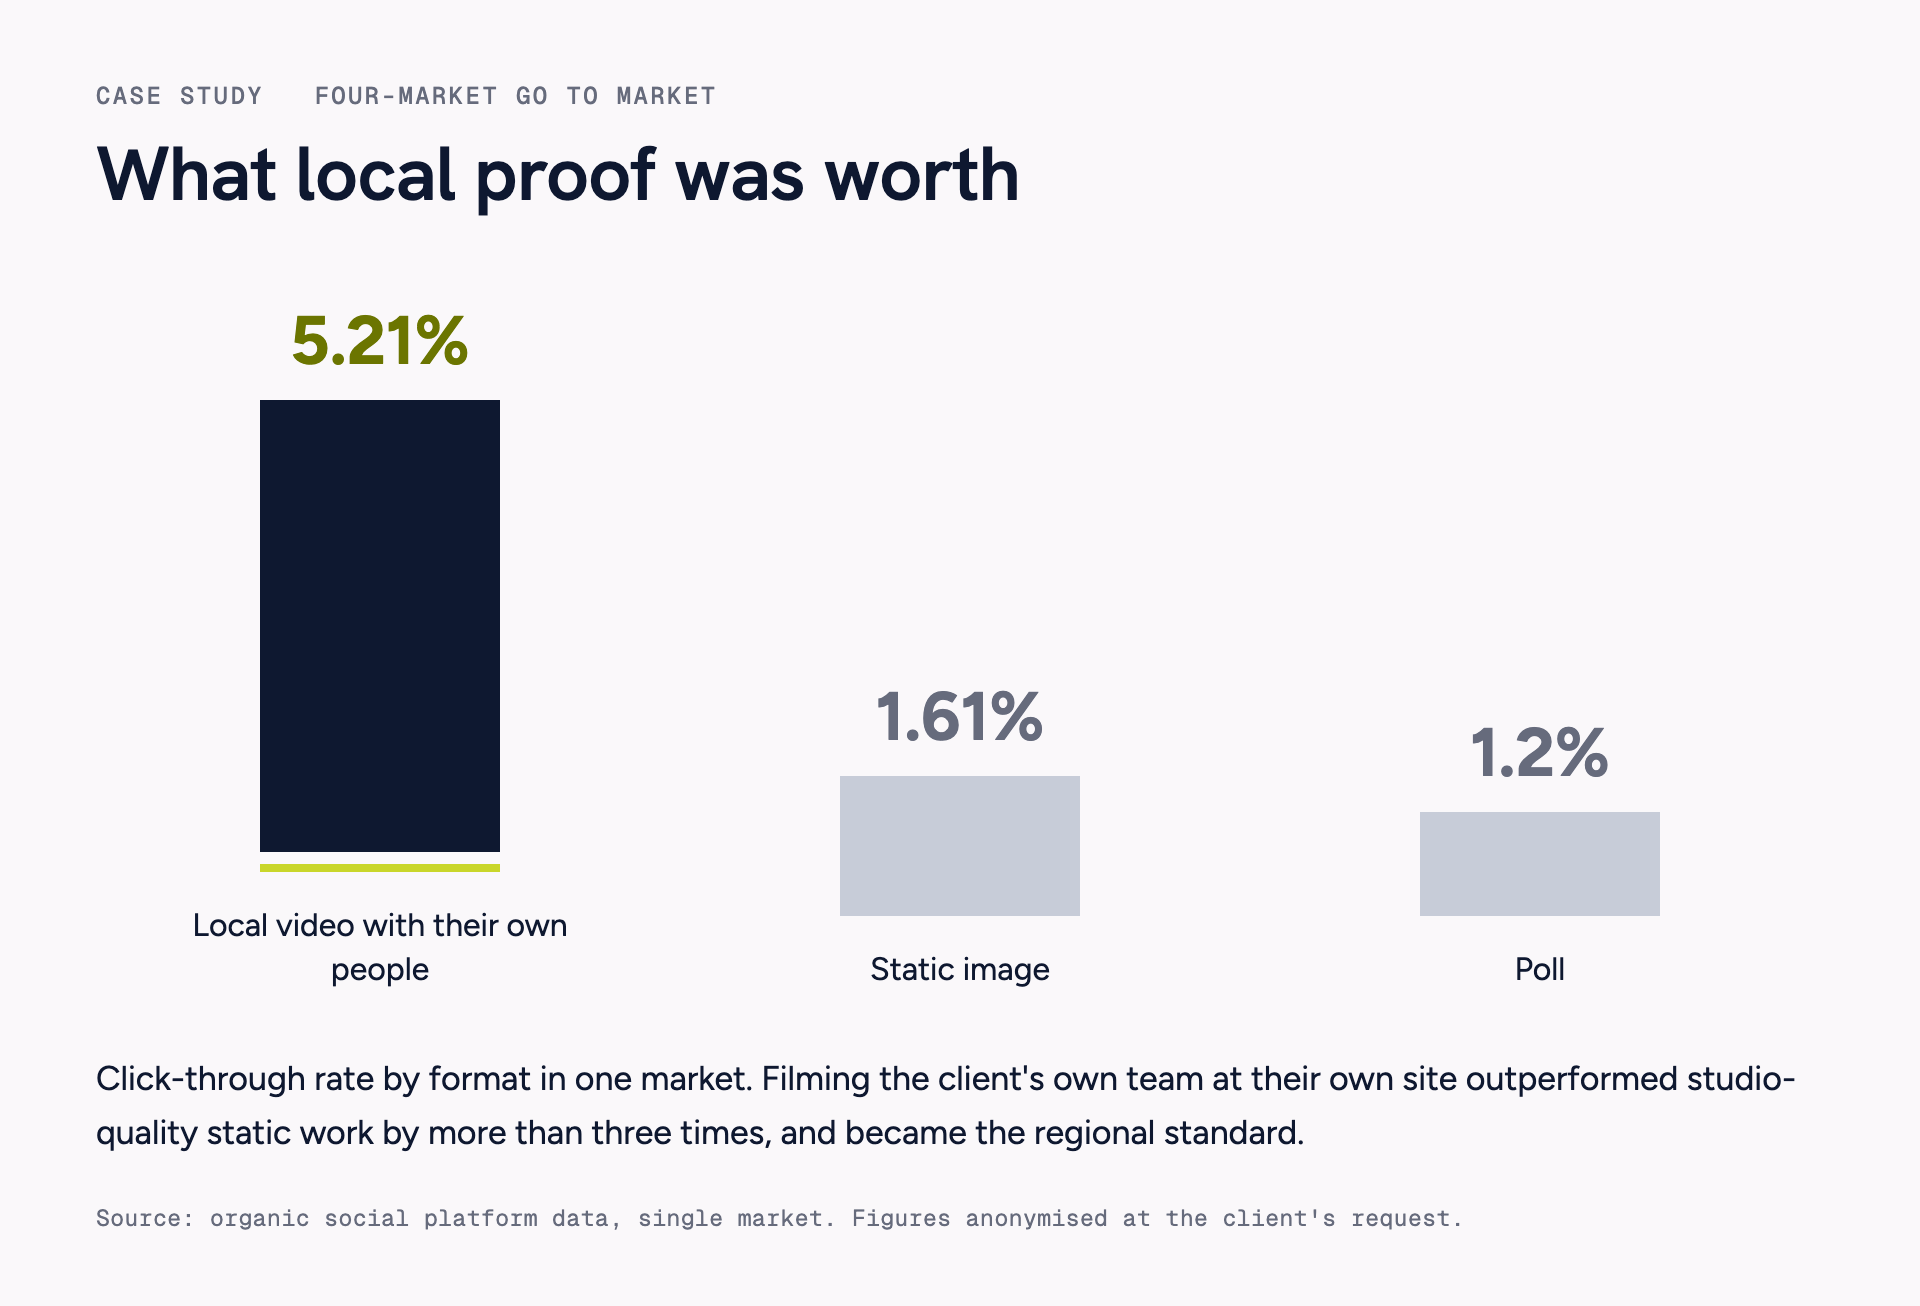
It outperformed produced static work by a wide margin, and cost less to make. The engagement rate was not the point though. The commercial effect was. Sales stopped having to argue that the local operation existed, because prospects had already seen it. Verifiable proof replaced an assertion, and that removed friction from the top of every conversation.
The format is now applied across the region. It began as a fix for one market’s credibility gap and became the standard, which is the most durable kind of result: the work outlived the campaign that produced it.
What we would tell you honestly
Experienced buyers price it as one. We include this section in every case study: what is still unproven, what we would do differently, and what is not ours to claim.
Lead flow is still not predictable across all four countries. We can generate leads. We cannot yet promise a number per month per market, and anyone promising that during a category build is guessing.
Attribution is the real gap. Limited funnel reporting and no automated nurturing for most of the period. We can prove attention. Proving pipeline needs plumbing that is still being built.
Budget continuity hurt the first phase. Fragmented allocation meant campaigns stopped before they could compound, and the clearest lesson of the year is that consistency of spend mattered more than size of spend.
Sales and marketing alignment still varies by country. The relationships are good. Shared processes and common definitions are not there yet.
And four markets at four maturity levels is genuinely hard. We underestimated the coordination cost in the first quarter of the expansion.
How we work
Execution has been commoditised. AI writes, designs and ships at close to zero marginal cost. What has not commoditised is the decision underneath: which market to enter, what the actual problem is when the brief says something else, and which local truth deserves to override the central plan.
Every one of those is made under real uncertainty, and AI does not reduce that uncertainty. It reduces the feeling of it, by returning a confident answer to a question whose honest answer is a range.
So the scarce skill is not producing more. It is judgement. Knowing which outcome you could not survive, which number in the plan is a range in disguise, and when the person in the smallest market is right and the central strategy is wrong.
That is what business knowledge actually is, and it is why we start with commercial reality rather than the creative brief. A good model cannot rescue a bad strategy. It only gets you lost faster, and it does it fluently.
In this engagement, the most valuable thing we did all year was listen to four local teams and let one of them change the plan for the region.